 Follow Us on Google News


 Follow Us on Google Discover
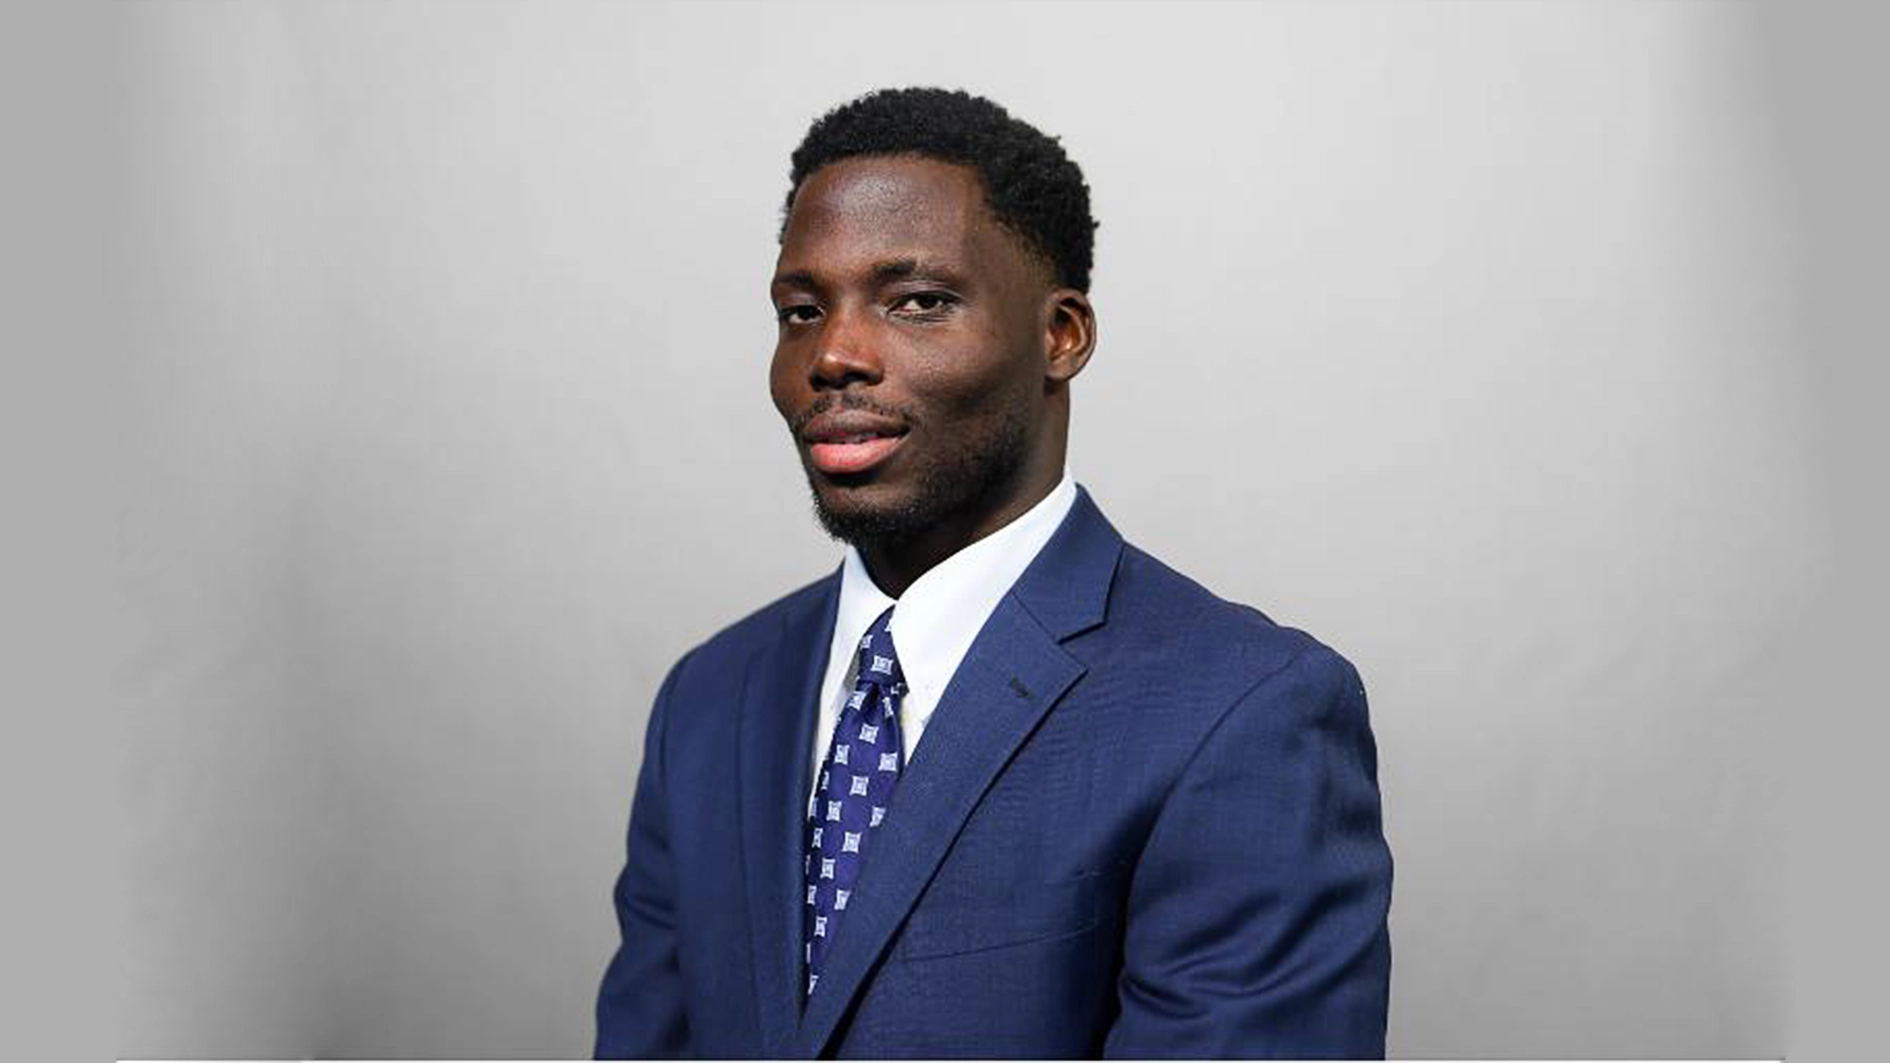
Every time a Nigerian asks a chatbot for help in Yoruba, applies for a loan through an app or describes symptoms to a digital health service, a decision made long before shapes the answer: what data the machine was trained on. Get that decision wrong, and even the most powerful artificial intelligence will misread the very people it is meant to serve. It is this hidden but decisive step that Nigerian data and artificial intelligence expert Serif Oyindamola Oyesiji has placed at the heart of Nigeria’s AI ambitions.
Mr Oyesiji, who is urging developers and policymakers to treat data selection as a matter of governance rather than a back-office task, set out his case in a peer-reviewed paper, “A Conceptual Framework for Context-Aware Data Curation in Fine-Tuning Pipelines,” published on 25 November 2024 in the International Journal of Engineering and Modern Technology.
The paper, which he co-wrote with Stanley Nwakamma and John Ojukwu, sets out how organisations should select, check and govern the data used to adapt AI systems for specific tasks and communities.
The issue has moved to the centre of Nigeria’s technology agenda. In April 2024, the Minister of Communications, Innovation and Digital Economy, Dr Bosun Tijani, announced the country’s first multilingual large language model, backed by $3.5m in seed funding, to be trained in five low-resource languages and accented English to ensure “stronger language representation in existing data sets.”
The project, led by local AI firm Awarri with government agencies and private partners, is supported by more than 7,000 fellows of the 3 million Technical Talent programme.
“Nigeria cannot simply borrow AI built on other people’s data and expect it to understand us,” Mr Oyesiji said. “If we are building our own models, the most important decisions happen before training begins, when we choose what the model will learn from.”
Large language models, which power chatbots and AI assistants, are trained on huge volumes of general text before developers’ “fine-tune” them on smaller datasets for specific jobs, such as answering banking enquiries in Yoruba or summarising patients’ records in a Nigerian hospital.
According to Mr Oyesiji, the quality of that smaller dataset often determines whether the finished system is accurate, biased or unsafe. The paper notes that most fine-tuning pipelines focus on the volume and general quality of data while overlooking six factors: the purpose of the task, the conditions of the sector it serves, the people who will use it, how information changes over time, the limits of where it will run, and the risks it carries.
To address the gap, the framework proposes seven linked stages. These are defining the context, finding suitable data, tracing its source, assessing its quality, auditing how fairly different groups are represented, selecting the most relevant examples and feeding real-world results back into the process.
It also targets common weaknesses in AI training, including duplicated records, unreliable labels, lopsided datasets and “contamination,” where test material leaks into training data.
The authors argue that success should be measured on four counts, namely usefulness on the real task, how closely a model’s confidence matches its accuracy, robustness and fairness. They describe data curation as “a continuous, auditable, and risk-sensitive control process” rather than a one-off cleaning exercise.
“A dataset can be perfectly clean and still be wrong for the job,” the researcher said. “A Hausa health dataset gathered in one region may not work for patients in another. Context-aware curation means asking those questions systematically, not as an afterthought.”
Mr Oyesiji noted that the approach could be especially useful in regulated sectors such as banking, health and public services, where organisations may increasingly be required to explain how their AI systems work. A documented record of why each piece of data was chosen, he explained, gives auditors and regulators something concrete to examine.
The framework builds on his earlier work on local-language AI. In 2023, Mr Oyesiji was lead author of a survey on adapting compact, on-device language models to multiple languages at low cost. Since 2020, he has authored or co-authored nine peer-reviewed papers on subjects including AI governance, the security of AI agents, cyber risk in Nigeria’s insurance sector and ransomware defence for industrial systems.
He has served as a section editor for computer science and engineering journals since 2021, and was admitted as a Fellow of the Chartered Institute of Information and Strategy Management in November 2024. He works as a Data and Insights Research Officer at FrieslandCampina WAMCO, Lagos.
Mr Oyesiji’s framework also aligns with the draft National Artificial Intelligence Strategy, which the Federal Government released in August 2024. The document, developed by the ministry with the National Centre for Artificial Intelligence and Robotics and the National Information Technology Development Agency, commits to “implementing global data quality standards” and to principles of “privacy, consent, fairness, and transparency” in the use of data for AI.
As government agencies, banks and start-ups begin to adopt AI tools, he said, the quality of training data has become a matter of public interest rather than a technical detail.
“Data curation should be treated as part of AI governance, not just an engineering chore,” Mr Oyesiji added. “Getting the data right is how we make sure these systems work for the people they are meant to serve.”