 Get Guardian on Google
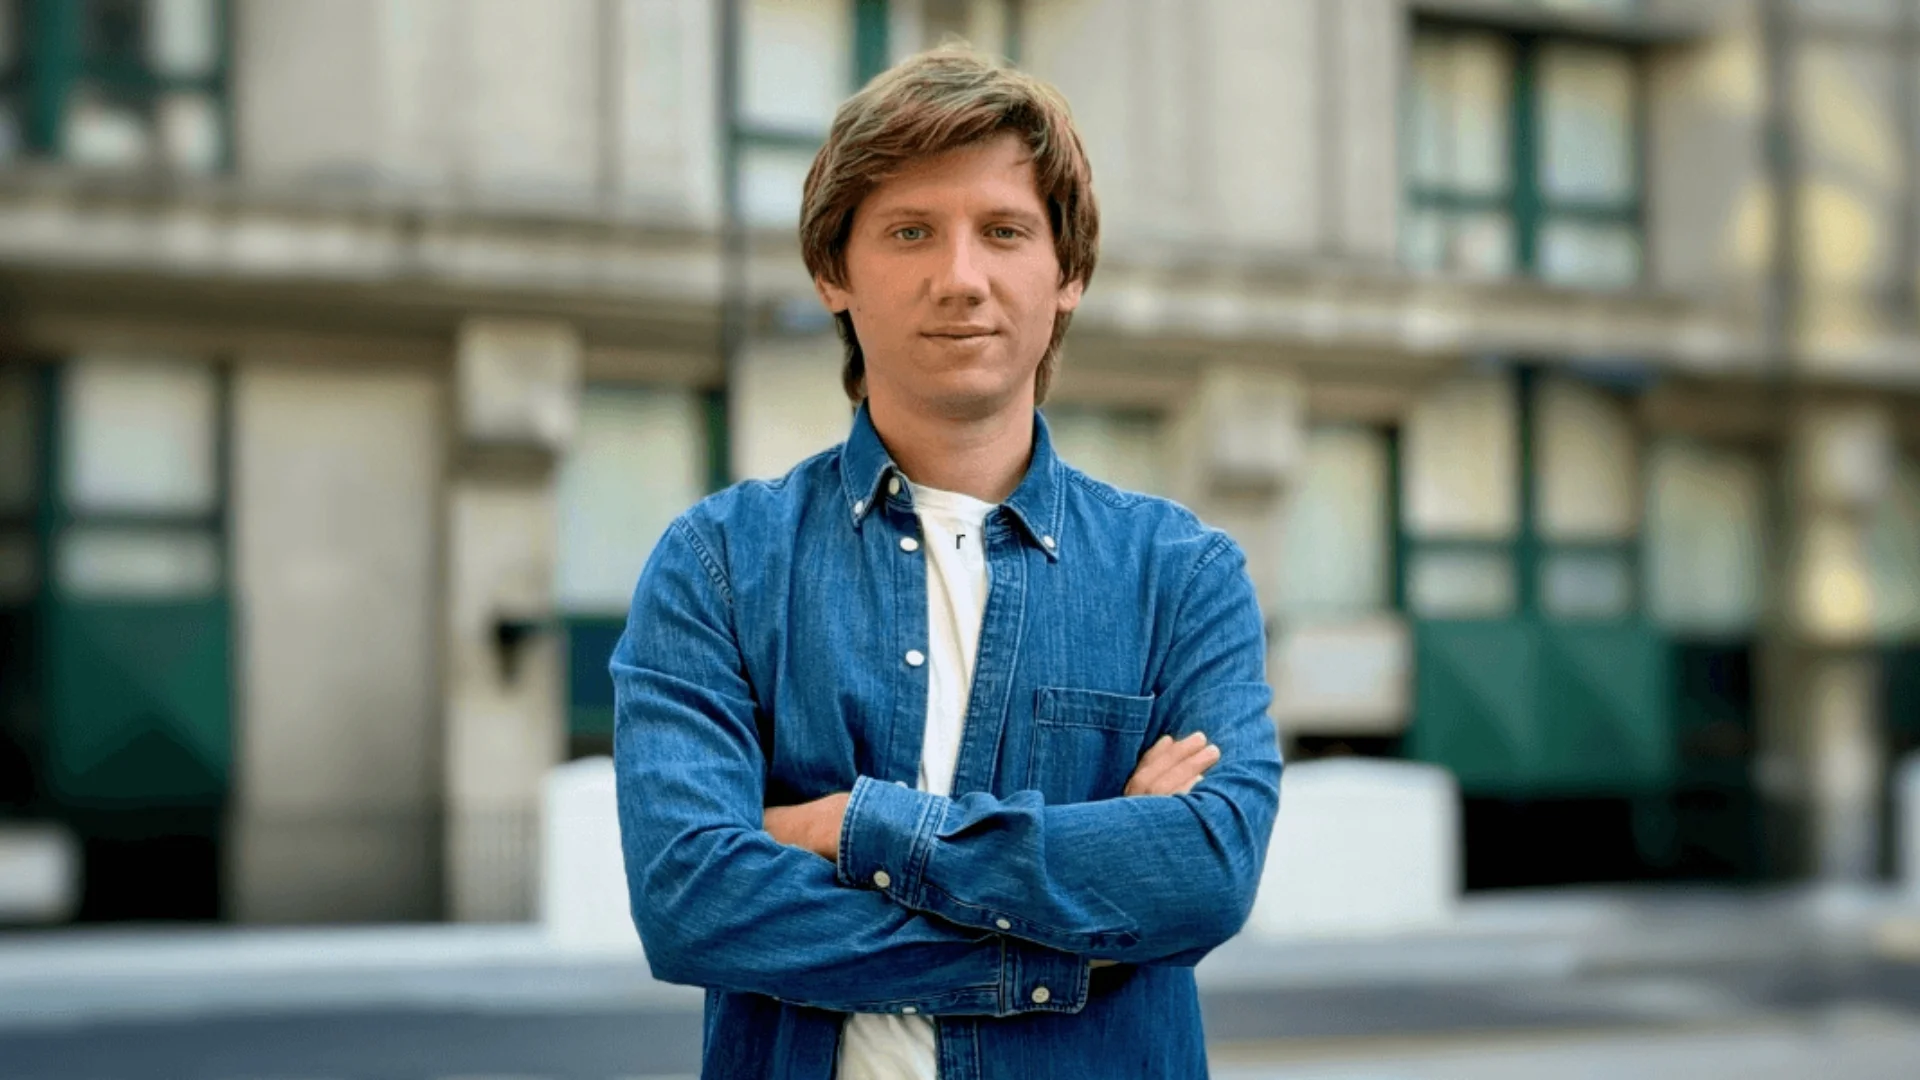
Explore the global challenges and hidden risks of AI adoption with Daniil Mazepin, a CoreWeave engineering leader and mentor to emerging African tech talent, as he explains why companies struggle to know whether AI agents are delivering reliable results.
Nigeria is bringing artificial intelligence into public services and banking. The Federal Government has introduced Service-Wise GPT to help civil servants find official rules and guidance, while GovGuide Nigeria is designed to help citizens navigate government services in English, Hausa, Igbo and Yoruba. Sparkle Bank’s technology provider says its AI agent handles routine customer enquiries and creates support tickets.
These launches raise a harder question: how will organisations know whether the tools are giving the right answers and solving people’s problems?
Daniil Mazepin, an engineering leader at CoreWeave, argues that this is now one of the industry’s central challenges. AI agents can fix bugs, handle support requests and take other actions. But they can appear to work normally while producing poor results. For Mazepin, building an agent is no longer the whole challenge. It is knowing when it stops delivering value.
Mazepin has spent about fifteen years building software used by millions of people. His experience includes mobile products at Playtech, the global rollout of Shops at Meta and a payments product at UK fintech Teya. Today, he leads engineering at CoreWeave, on the team building its Physical AI platform. His focus is the gap between an agent that impresses once and one a business can rely on. He also mentors emerging tech talent through GMI and speaks at Schoolville, working with early-career engineers and founders in Africa who are building with these tools from day one.
“Most of the advice on observing AI systems is being invented from scratch right now, and a good deal of it was solved a decade ago at hyperscale,” Mazepin said. “AI didn’t break observability. It gave every team hyperscale’s failure modes, without hyperscale’s habits.”
Traditional monitoring assumes that the same input produces the same output, that a result can be marked as a pass or fail, and that a breakdown will trigger an error. Agents challenge all three assumptions. They can respond quickly with a perfectly healthy response, show no obvious error and still be wrong.
Mazepin warns that an agent’s quality can decline while its dashboards continue to show it as healthy, leaving users to notice the problem first.
Large infrastructure operators encountered similar “gray failures” years before generative AI. In 2017, Microsoft researchers used the term to describe systems whose own failure detectors report them as healthy while the applications that depend on them struggle. Meta and Google have also written about processors that silently return wrong answers without crashing or raising an alert.
“At fleet scale, even hardware stops being deterministic, and failures become rates rather than events,” Mazepin said. AI teams, he argues, need to stop treating “no errors” as proof of health and learn the same lesson now, only much faster, because an agent can take actions on its own.
Beyond the demo
Mazepin is blunt about how much of the industry still judges agents. According to him, a successful demo proves little about how an agent will perform in everyday use. Someone may have chosen the ideal input and shown the best result. Real-world use means repeated attempts, messy requests and failures that may happen when nobody is watching;
“Anyone can build an impressive demo now,” Mazepin said. “The skill is knowing whether the agent is still valuable on the thousandth run. “Don’t ask ‘did it work’. Ask ‘out of a hundred real attempts, how many did it get right’.”
His proposed test is to count how often an agent gets a task right across many real-world attempts. An 80 per cent success rate and a 99 per cent success rate describe different products, he says, and whether either is acceptable depends on the consequences. A lower rate may be tolerable for a low-risk task. For something involving money, health or safety, even a small error rate can matter; in some cases, even a 99 per cent success rate is not acceptable.
The same criticism applies to the numbers teams report once an agent is live. Requests handled, lines of code generated and emails written are, in Mazepin’s view, mostly noise. “Those numbers tell you the machine was busy. They don’t tell you anything good happened,” Mazepin said. “If your metric goes up while the agent does nothing useful, it’s an activity metric. Throw it away and measure the outcome a real person can feel.”
Choosing what to automate
For Mazepin, observability starts before launch, with the choice of task. Before automating a task, he suggests checking whether it happens often, whether the result is easy to verify and whether getting it right matters to someone. He calls these tests volume, verifiability and value.
Verifiability is the one he returns to most. “It’s the one people forget, and it’s the most important,” Mazepin noted. “Agents are sometimes wrong. The question is whether you’ll catch it before it causes damage, and what catching it costs. If you can’t check the work, you’re not automating the task. You’re just gambling faster.”
Mazepin points to code that either passes its tests or doesn’t, and totals that either add up or don’t. These are good places for agents because a wrong answer is cheap to catch. Medical advice, legal documents and hiring decisions are the opposite. They are hard to check, and the damage is done before anyone notices, so a human should stay in the loop.
Value is where Mazepin sees the most wasted effort. “People automate things that don’t matter, and then wonder why nobody uses the tool,” Mazepin added. “If you can’t name the person who benefits and the number that moves, you don’t have a target. You have a toy.”
Mazepin draws on his own experience at Meta to explain why teams need to measure the whole user journey. During the rollout of Shops, different teams had separate dashboards, but an error at checkout mattered more than one during product discovery. “We realised that a mistake at the checkout button costs far more than one on the first screen of discovery,” Mazepin said. The answer was a single metric the teams called revenue uptime, which, among other things, weighted errors by the step of the journey where they happened. A horizontal team owned it, and it gave many teams one shared view of what mattered most.
Mazepin sees the same pattern in AI agents. Agents also carry out multi-step tasks: they plan, gather context, call tools, make changes and return an answer. Each step can look fine on its own while the outcome is still wrong, so the number that counts is whether the whole run delivered what the user needed. “At Meta, measuring whether a journey like that worked end to end was a cross-team problem, with a dedicated team to own it,” Mazepin said. “Today a single engineer building an agent has to solve the same problem alone, and most don’t realise they’ve inherited it.”
The answer is to define success from the user’s perspective and measure the outcome, not just the steps. For a coding agent, that might be a pull request that is merged and not reverted within 48 hours. For a support agent, it might be a ticket resolved without a human taking over, and not reopened within seven days. “A destructive tool call should weigh far more than an answer that’s a bit too wordy,” Mazepin said. “It’s checkout versus discovery again.”
Measuring after launch
The industry is investing in tracing, dashboards and evaluation tools. Mazepin welcomes these, but says technology vendors cannot decide what “right” means for an organisation’s users. Teams have to define success, put it into a measure and agree who responds when performance slips. “You have to decide that, write it down as a number and agree who gets paged when it drifts. Most teams skip that part.” he explains.
He recommends setting a baseline before launch, measuring how much results vary, running tests with known answers alongside real traffic, and alerting on deteriorating rates rather than one-off scores. Teams should introduce changes gradually and turn incidents into new evaluations. They should also count the cost of checking results and correcting mistakes.
The cost of being wrong is the one Mazepin calls the killer. “Imagine an agent that does a task in one second instead of ten minutes, but it’s wrong one time in five,” Mazepin said. “Every time it’s wrong, a human has to notice, undo the damage and redo it. Suddenly your fast agent creates more work than it saves. A fast, unreliable agent doing a task nobody checks is not a productivity gain. It’s a liability with good marketing.”
Not every AI task has one objectively correct answer, and teams may use another model to evaluate a system’s output. Even the definition of a good result can shift. Mazepin’s answer is to keep measuring as systems and expectations change. An agent that worked well in March may perform worse by June, he says, and teams may not notice if they stop checking.
That is why he sees ongoing evaluation as a scarce skill. In Mazepin’s view, building an agent is no longer the hard part. The hard part is deciding what “right” means to the person using it and noticing when the agent stops delivering it. “In physical AI, a silent failure isn’t a wrong answer in a chat window,” Mazepin said. “It’s a machine confidently doing the wrong thing in the real world.”
Mazepin also credits the parts of the industry that are getting this right. “The most useful thing some AI companies have done recently is publish honest postmortems where every check passed and users noticed first,” Mazepin said. “That’s the hyperscale habit worth copying. Admit the dashboard was green, and fix the measurement, not just the bug.”
For Nigeria, where AI tools are being introduced in public services and business, and where the engineers Mazepin mentors will be among those building and running them, the question is not only what the systems are designed to do. It is how their owners will know whether they are doing it accurately, consistently and usefully.
“The teams that win aren’t the ones with the cleverest agent,” Mazepin said. “They’re the ones who keep watching and catch the drift before their users do.”